





A fast multiprocessing.Queue alternative for large Python objects and NumPy arrays.
Payloads travel between processes through shared memory instead of pipes; the queues
underneath carry only a few bytes of metadata per message. Multi-megabyte batches,
images, and simulation states arrive up to 3.5× faster on Windows and up to 7.9× faster on
Linux, on macOS even small messages beat a bounded multiprocessing.Queue, and transfers
too large for multiprocessing.Queue still work.
- Familiar API:
put/getwithblock,timeout,put_nowait/get_nowait,queue.Full, andqueue.Empty. - Any picklable object: NumPy arrays, other protocol-5 buffers, and large
bytesandbytearrayobjects are copied straight into shared memory, without an intermediate pickle copy. - Bounded memory: a capacity limit applies backpressure, and received blocks are
reused for later messages, so shared memory stays within
capacity × message size. - One producer, many consumers: consumer processes and threads share one receiver.
- Portable: Linux, macOS, and Windows on x86-64 and ARM64;
spawn,fork, andforkserver; Python 3.11–3.15, including free-threaded 3.15t. - Lightweight: no dependencies, fully typed (PEP 561), and 100% test coverage.
Built for machine-learning data pipelines, reinforcement-learning actors and replay buffers, scientific computing, and image or video processing, where large payloads make pipe I/O the bottleneck.
pip install py-sharedmemoryUpgrading from 3.x? The import package is now
py_sharedmemory(previouslymemory). Replacefrom memory import ...withfrom py_sharedmemory import ...; the API is otherwise the same.
import multiprocessing as mp

from py_sharedmemory import create_shared_memory_pair


def produce(sender):
    with sender:
        sender.put({"step": 42, "frames": bytearray(16_000_000)})
        sender.wait_for_all_ack()  # Keep the data alive until it is received


if __name__ == "__main__":
    ctx = mp.get_context("spawn")
    sender, receiver = create_shared_memory_pair(capacity=2, ctx=ctx)
    worker = ctx.Process(target=produce, args=(sender,))
    worker.start()
    with receiver:
        batch = receiver.get(timeout=30)
    worker.join()
    sender.close()
More complete, runnable programs:
examples/basic.py: a producer process with timeouts and error handling.examples/numpy_batches.py: streaming NumPy batches with backpressure and an end-of-stream marker.examples/worker_pool.py: fanning large tasks out to several consumer processes.
Use py-sharedmemory when individual messages are about 1 MB or larger on Linux and
Windows; on Windows ARM64 it pulls clearly ahead from about 10 MB. Typical payloads are
NumPy arrays, image or video frames, RL rollouts, large bytes, or big nested objects. On
macOS it was faster at every size measured, from 1 kB up; see
Performance.
On Linux and Windows, prefer multiprocessing.Queue for small messages: up to about
100 kB it is 1.5–3.6× faster, because handling a shared-memory block for every message
costs more than the pipe.
On free-threaded Python (python3.14t and later), threads run Python code in parallel.
If everything your workers use is free-threading safe, threads and queue.Queue pass
objects by reference without any copy. Use processes, and this package, when you need
process isolation or rely on extensions that re-enable the GIL.
To let several processes read and write the same array in place, use
multiprocessing.shared_memory
directly. py-sharedmemory delivers an independent copy of each message.
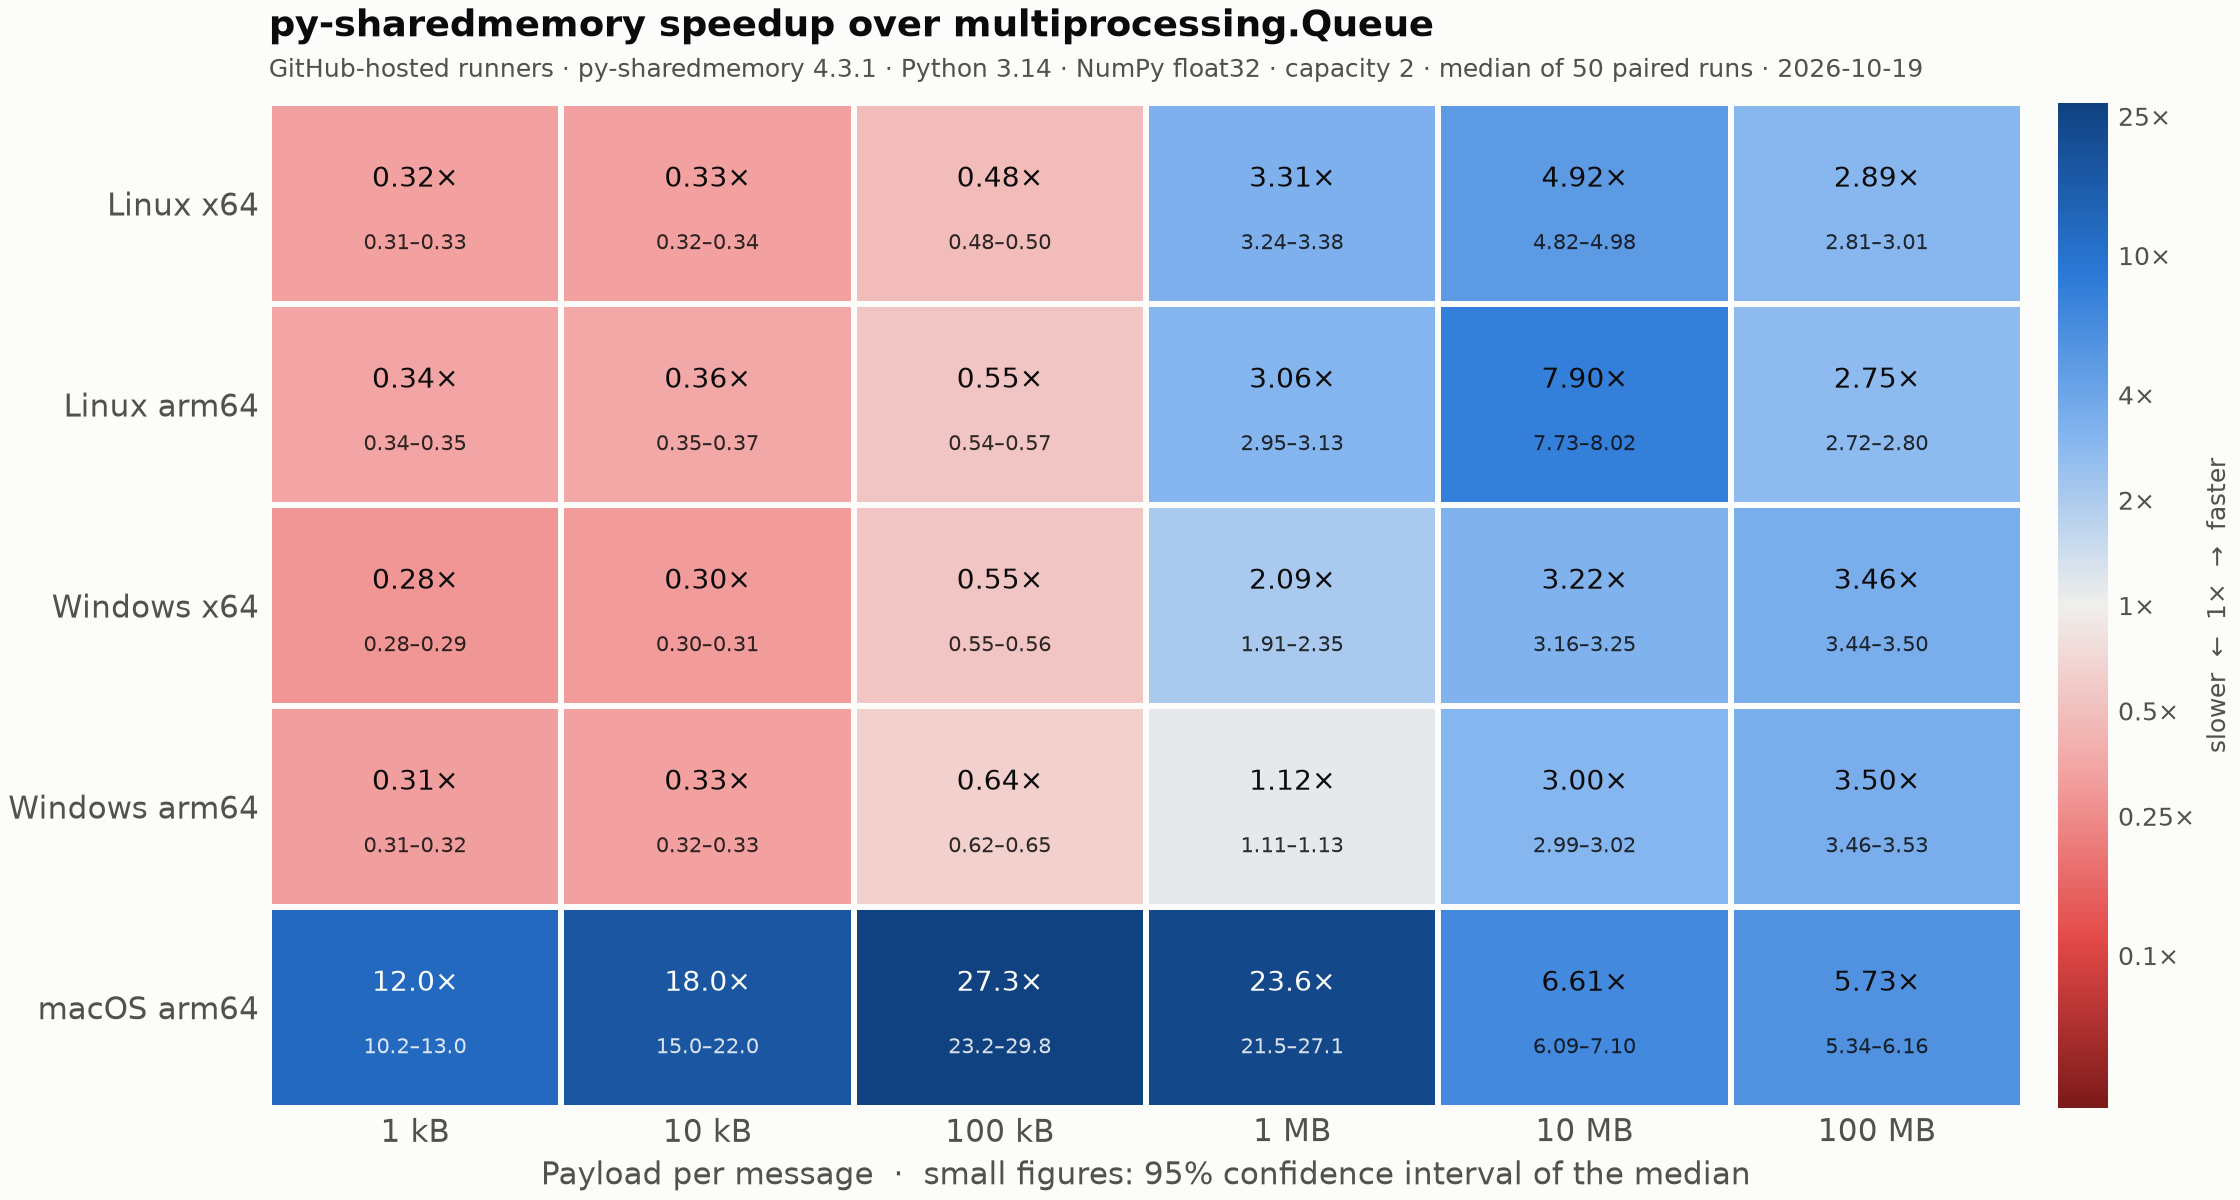
Speedup over multiprocessing.Queue; above 1× means py-sharedmemory is faster. Each cell
is the median of 50 paired runs, with the 95% confidence interval of that median in
parentheses.
| Platform | 1 kB | 10 kB | 100 kB | 1 MB | 10 MB | 100 MB |
|---|---|---|---|---|---|---|
| Linux x64 | 0.32× (0.31–0.33) | 0.33× (0.32–0.34) | 0.48× (0.48–0.50) | 3.31× (3.24–3.38) | 4.92× (4.82–4.98) | 2.89× (2.81–3.01) |
| Linux arm64 | 0.34× (0.34–0.35) | 0.36× (0.35–0.37) | 0.55× (0.54–0.57) | 3.06× (2.95–3.13) | 7.90× (7.73–8.02) | 2.75× (2.72–2.80) |
| Windows x64 | 0.28× (0.28–0.29) | 0.30× (0.30–0.31) | 0.55× (0.55–0.56) | 2.09× (1.91–2.35) | 3.22× (3.16–3.25) | 3.46× (3.44–3.50) |
| Windows arm64 | 0.31× (0.31–0.32) | 0.33× (0.32–0.33) | 0.64× (0.62–0.65) | 1.12× (1.11–1.13) | 3.00× (2.99–3.02) | 3.50× (3.46–3.53) |
| macOS arm64 | 11.96× (10.20–13.04) | 18.04× (14.98–21.99) | 27.29× (23.23–29.80) | 23.64× (21.48–27.08) | 6.61× (6.09–7.10) | 5.73× (5.34–6.16) |
- Linux, x86-64 and ARM64: 2.8–7.9× faster from 1 MB. Up to 100 kB,
multiprocessing.Queueis 1.8–3.1× faster. - Windows x86-64: 2.1–3.5× faster from 1 MB, and 1.8–3.6× slower up to 100 kB.
- Windows ARM64: slightly faster at 1 MB, and 3–3.5× faster from 10 MB.
- macOS (Apple Silicon): 5.7–27× faster at every size. macOS has no timed semaphore
wait, so a full bounded
multiprocessing.Queuewhoseputhas a timeout, as here, polls with sleeps of up to 20 ms. py-sharedmemory enforces its capacity with a thread condition instead.
Measured by the benchmark workflow
on GitHub-hosted runners on 2026-10-19: py-sharedmemory 4.3.1, Python 3.14.8, NumPy 2.5.4,
contiguous float32 arrays, spawn, and capacity 2 for both queues. Each run sends the same
messages through both queues back to back, alternating which goes first, and the ratio of
their times is one speedup; pairing them cancels most of the drift of the shared virtual
machines, whose absolute throughput says little. The intervals are distribution-free,
from the order statistics of the 50 speedups. See the
raw results.
The workflow reruns with 20 runs on every release.
Larger messages: the speedup holds beyond the 100 MB that shared runners can hold. On
a Windows desktop, an earlier version stayed 1.8× faster at 100 MB and 1.5× faster at 1 GB,
and at 10 GB per message multiprocessing.Queue failed while py-sharedmemory delivered
each message in 7.5 s (raw results).
put()pickles the object with protocol 5. Large buffers, such as NumPy array data andbytesorbytearrayobjects of 64 KiB or more, never enter the pickle; everything is copied once, from the original objects into one shared-memory block: a block from an earlier, received message when one fits, otherwise a new one.- Only the block's name and identity, the buffer sizes, and a sequence number travel
through a
multiprocessing.Queue. get()maps the block, or reuses its mapping from an earlier message, copies the data into local memory, unpickles it, and sends an acknowledgement back.- A background thread in the producer makes the block available for reuse when the
acknowledgement arrives.
capacitylimits how many messages can be outstanding.
Received objects never point into shared memory, so they stay valid after the block is reused or freed and can be modified freely.
Create the pair in the parent process and pass the endpoints to workers as Process
arguments, the same way as a multiprocessing.Queue. Use the same context for the pair
and the processes. A sender can be passed to another process only before its first
put; after that it belongs to the process that used it.
As with a multiprocessing.Queue, keep an endpoint referenced in the creating process until
the processes using the pair have started. With spawn and forkserver on Linux and macOS,
a starting child reopens the pair's semaphores by name, and the names disappear once the
creating process lets go of them. After that, the creating process may drop endpoints it
does not use, and may create as many further pairs as it needs.
Closing an endpoint affects only that endpoint. As with the unused end of a Pipe, the
parent may close its copy of the endpoint it handed to a child right after starting the
child, and keep using the other endpoint. A process releases its handles to the pair when
its last open endpoint closes.
ctx = mp.get_context("spawn")  # "fork" and "forkserver" also work
sender, receiver = create_shared_memory_pair(capacity=4, ctx=ctx)
producer = ctx.Process(target=produce, args=(sender,))
consumer = ctx.Process(target=consume, args=(receiver,))capacity counts messages that were sent but not yet received. When it is reached,
put() blocks, so a fast producer cannot exhaust memory. Shared-memory use is at most
about capacity × message size. capacity=0 or None means unbounded.
Received blocks are reused rather than freed, because writing into memory that is
already mapped is much faster than faulting in fresh pages. A block is reused for a
message that fills at least half of it, or for any message that fits a block of up to
1 MiB. The sender keeps at most 8 such blocks and 256 MiB, never more blocks than the
capacity allows, and frees them on close(). Blocks over 256 MiB are freed once received.
Receivers likewise keep the blocks they read mapped instead of mapping them again for
every message: each receiving thread keeps at most capacity (up to 8) blocks and
256 MiB, and close() releases them. On Windows, where a block lives while any process
maps it, a receiver therefore keeps a block its sender has freed alive until the receiver
reads other blocks or closes.
from queue import Empty, Full

try:
    sender.put(batch, timeout=5)  # Wait up to 5 s for capacity
except Full:
    ...

try:
    item = receiver.get_nowait()  # Same as get(block=False)
except Empty:
    ...
timeout=None and timeout=math.inf both wait without limit. Negative timeouts behave
like 0, and a NaN timeout raises ValueError.
Each message is delivered to exactly one consumer. Several consumer processes can share
one receiver, as in examples/worker_pool.py,
and both endpoints are thread-safe. Only one process may produce per pair; for several
producer processes, create one pair per producer.
The producer owns every message until it is acknowledged, and close() frees unread
messages. Before the producer closes or exits:
with sender:
    for item in items:
        sender.put(item)
    if not sender.wait_for_all_ack(timeout=30):
        raise TimeoutError("Consumer did not receive everything")
Closing never blocks. If a with sender: block or the producing process ends normally
while messages are still unacknowledged, they are discarded and the sender emits a
RuntimeWarning, so forgetting to drain does not lose data silently. An explicit
close() or an exception leaving the with block discards without a warning.
When both endpoints live in one process, drain before closing the sender, because closing
it frees unread messages. A sentinel such as None is a simple way to tell consumers that
the stream has ended. A thread waiting in get() without a timeout wakes with
BrokenPipeError when its receiver is closed, and a daemon thread still waiting when the
program ends simply ends with it.
- Pass timeouts when a peer can die.
get,put, andwait_for_all_ackwithout a timeout wait forever for a process that no longer exists, as with amultiprocessing.Queue. - A crashed consumer loses at most the message it was handling. Messages it never received go to the next consumer, including one started to replace it. If the crash also lost that message's acknowledgement, its slot of capacity stays taken until the sender closes; closing still never blocks and frees every block.
- Killing an idle consumer is safe. Receivers wait for data without holding the queue's read lock, so the other consumers keep receiving.
- Stop consumers cooperatively when you can, for example with one sentinel each. A
consumer killed during the brief moment it reads a message, or on Linux and macOS while
its acknowledgement is being written, can still leave the pair's queue locked, just as
it would a
multiprocessing.Queue. - A crashed producer's unread messages stay readable on Linux and macOS, where a block
outlives its creator until it is unlinked. On Windows they are freed with the producer,
and
getraisesFileNotFoundErrorfor each of them.
Arrays keep their dtype, shape, and writability. Read-only arrays stay read-only, and writable ones arrive as writable local copies. C- and Fortran-contiguous arrays keep their layout and are copied straight into shared memory without an intermediate pickle copy; other views, such as strided slices, arrive as contiguous copies. Each received array has its own aligned memory, so keeping one array does not keep the rest of the message alive.
| Exception | Raised when |
|---|---|
queue.Full |
put found no capacity within timeout or with block=False. |
queue.Empty |
get found no message within timeout or with block=False. |
BrokenPipeError |
The endpoint is closed, the producer's acknowledgement channel failed, or the main thread was waiting in get while the process exits. |
FileNotFoundError |
get received a message that the producer freed by closing before it was read. |
OSError (ENOSPC) |
put found no room for the message in shared memory, for example a full /dev/shm in a container. The sender stays usable. |
ValueError |
A timeout is NaN. |
RuntimeError |
A second process tries to produce, or a used sender is passed to another process. |
| Pickling errors | The object cannot be pickled or unpickled. Both endpoints stay usable, and failed messages are still released. |
RuntimeWarning (warning) |
A with sender: block or the producing process ended normally and discarded unacknowledged messages. |
Returns a connected (SharedMemorySender, SharedMemoryReceiver). capacity limits
outstanding messages (0 or None is unbounded). ctx is the multiprocessing context
for the underlying queues; it defaults to multiprocessing.get_context().
| Member | Description |
|---|---|
put(obj, block=True, timeout=None) |
Copy obj into a shared-memory block and send it. |
put_nowait(obj) |
put(obj, block=False). |
wait_for_all_ack(timeout=None) -> bool |
Wait until every message is received and its block released; False on timeout. |
close() |
Free unread messages and reusable blocks silently and release resources. Leaves a receiver in the same process usable. Runs automatically at normal process exit. |
closed |
Whether the sender is closed. |
with sender: |
Closes the sender on exit; warns if a clean exit discards unacknowledged messages. |
| Member | Description |
|---|---|
get(block=True, timeout=None) |
Return the next object as an independent local copy. |
get_nowait() |
get(block=False). |
close() |
Release kept mappings, flush acknowledgements, and wake waiting get calls with BrokenPipeError. Leaves a sender in the same process usable. |
closed |
Whether the receiver is closed. |
with receiver: |
Closes the receiver on exit. |
Docker and Kubernetes: on Linux, shared memory lives in /dev/shm, which containers
limit to 64 MB by default. Raise it to at least capacity × largest message, for example
docker run --shm-size=2g or shm_size: 2gb in Docker Compose. In Kubernetes, mount an
emptyDir volume with medium: Memory at /dev/shm. Otherwise put raises
OSError: [Errno 28] No space left on device; the sender reserves a new block's pages up
front, so a full /dev/shm raises this error instead of killing the producer with SIGBUS.
Linux: outside containers, /dev/shm usually defaults to half of physical RAM.
macOS: fully supported and tested on Apple Silicon. The default start method is
spawn, so guard the entry point with if __name__ == "__main__":. An unbounded pair
holds at most 32,767 unread messages, the limit of macOS semaphores; beyond that put
waits or raises queue.Full like a full bounded pair.
Windows: shared memory is backed by the page file, and each block disappears once the last handle closes, so nothing can leak after a crash.
"resource_tracker: There appear to be N leaked shared_memory objects" (or semaphore objects): a process was killed or crashed before releasing the blocks or semaphores it created, and Python's resource tracker freed them when the program ended. Nothing stays behind; stop workers cooperatively, for example with a stop event, to avoid the warning.
FileNotFoundError: Shared-memory block was freed before it was received: the
producer closed or exited before this message was read. Call wait_for_all_ack() before
closing the sender; the sender also warns when this happens.
OSError: [Errno 24] Too many open files: on Linux and macOS each pair costs a
process 4 file descriptors for its queues, on macOS a few more for its semaphores, plus 1
per block the sender keeps for reuse and 1 per block a receiving thread keeps mapped, each
at most capacity (up to 8). Unread messages beyond that hold none, and a receiver that
runs out releases its kept mappings and retries. For many pairs on macOS, whose default
limit is 256, raise it with ulimit -n.
RuntimeError: A shared-memory pair supports one producing process: a second
process called put. Create a separate pair for each producer process.
Can't pickle local object or similar: messages must be picklable. Lambdas, local
functions, open files, and locks cannot be sent.
Bug reports, ideas, and pull requests are welcome. See CONTRIBUTING.md for the development setup, tests, and release process, and the changelog for version history. Report security issues privately as described in SECURITY.md.
MIT © Tobias Würth