





ML backend engineer: I build the systems that serve, feed and secure models.
LLM inference on consumer GPUs, agent memory over MCP, LLM tutoring and AI-driven app testing, in Python and Rust, built end to end.




- 🧠 Gave AI coding agents a memory over MCP that answers a question in ~168 tokens instead of reading 38,921 tokens of source (~231x cheaper).
- 🎓 Turned any LLM into a calibrated tutor that remembers what you've mastered, shipped as a CLI on PyPI.
- 🧑 Built a tester that uses your app like a real person: typos, rage-clicks and locale mix-ups from 8 personas across web, CLI, API, chat and more, with zero runtime dependencies.
- 🚀 Run a 120B model at 28 tokens/s on an 8 GB laptop GPU: a llama.cpp extension that keeps hot MoE experts in VRAM, up to 2.1x faster than the best layer split.
- 🧪 Measured, tested and documented: I don't claim a number until a benchmark backs it.
🗂️ project-memory: long-term memory for AI coding agents
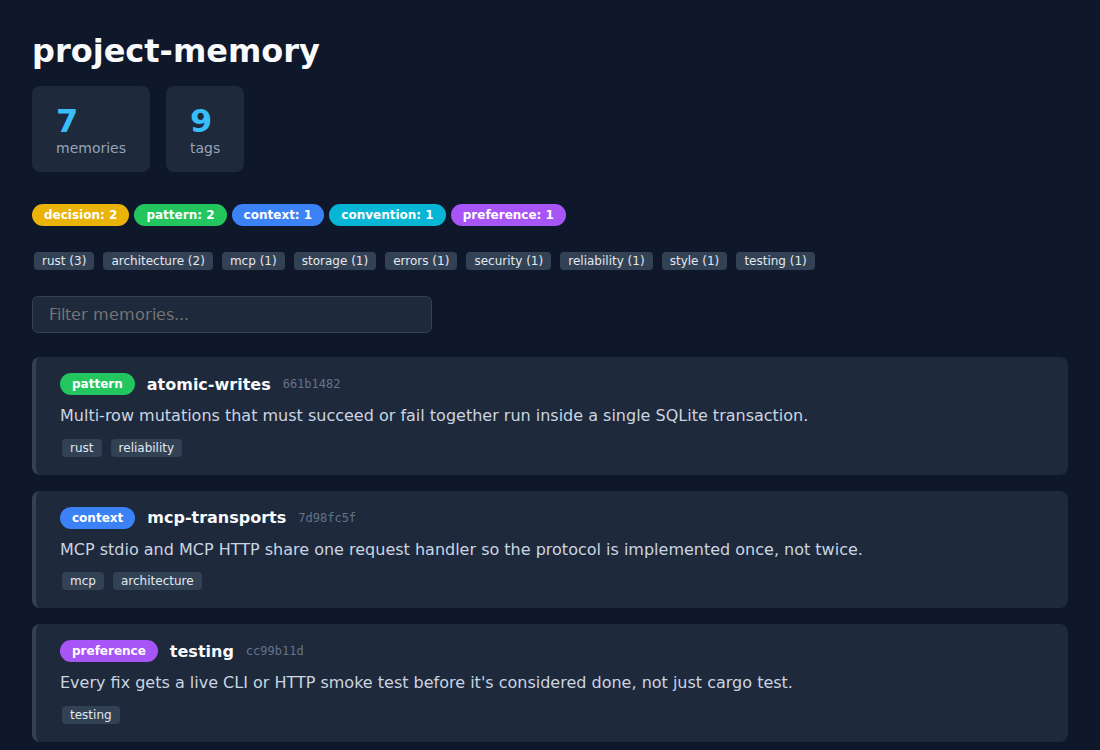
pmem stores a project's conventions, decisions and patterns in SQLite and serves them to any MCP client (Claude Code, Cursor, OpenCode), so an agent stops re-reading the codebase every session.
- ~231x cheaper than reading the source: 50 real questions averaged 168 tokens each, and every one found its answer.
- Fuzzy and full-text search, snapshots, duplicate detection, AES-256-GCM encryption and a web dashboard, in a 9.9 MB Rust binary.
Rust MCP SQLite AI agents
🎓 expert-mentor: turn any LLM into a calibrated tutor
A CLI on PyPI that turns Claude, ChatGPT, Gemini or a local Ollama / llama.cpp model into an expert mentor for any field. It writes provider-native prompts, runs the session, remembers what you've mastered and quizzes you with spaced repetition.
pipx install expert-mentorPython Prompt engineering LLM APIs Claude Code skill
🧑 human-like-ai-tester: test your app like a real, messy human
A Python CLI and library on PyPI that tests web apps, CLIs, APIs, chatbots, desktop and mobile apps and data pipelines the way people actually use them: adjacent-key typos, (555) 234-5678 in digit-only fields, rage-clicks after 1.5 s of silence, Back-button navigation and 12/05/2026 read in the wrong locale.
- 8 personas, from a rushed commuter to a screen-reader user, each with its own typo rate, patience and habits.
- One merged audit: a multi-persona sweep produces a single deduplicated Markdown and JSON report.
- Agent-ready: ships LLM prompts and an agent skill so an AI agent can run the same human-style test session.
- Zero runtime dependencies, 71 network-free tests and CI on Python 3.9 to 3.13.
pip install human-like-ai-tester
human-tester demo
Python AI agents QA automation Accessibility
🚀 extended-strata-moe: big MoE models on a small GPU
Extends Strata from one model to every Mixture-of-Experts architecture llama.cpp supports (DeepSeek, Qwen3 MoE, gpt-oss, GLM, Llama 4, Kimi and more). The experts a conversation actually uses stay cached in VRAM, the CPU computes the misses from system RAM at the same time, and the two sync through a 3 µs CUDA mailbox, so nothing is uploaded over PCIe during generation.
| RTX 4060 Laptop, 8 GB VRAM | Best llama.cpp layer split | extended-strata-moe |
|---|---|---|
| gpt-oss-120b (63 GB) | 15.9 t/s | 28.2 t/s (+77%) |
| Qwen3-Coder-Next 80B (65.6 GB) | 17.8 t/s | 37.2 t/s (+109%) |
Verified on 53 MoE architectures with KL divergence under 0.002 against CPU-only evaluation. It serves OpenAI- and Anthropic-compatible APIs, so Claude Code or Cursor can use it directly.
C++ / CUDA Python llama.cpp LLM inference
I'm self-taught and learned by building real projects instead of tutorials. For every project, I:
- Start with the hard problem. GPU memory scheduling, agent context, human error: the part most people would outsource.
- Measure it. Every number above comes from a benchmark in the repo.
- Make it runnable. One-command setup, CI, releases and docs, so someone else can use it without asking me.
Hiring for a remote ML backend or ML infrastructure role? I'd like to hear about it.
📫 salihyilboga98@gmail.com · 🌐 portfolio.voidstackloop.com